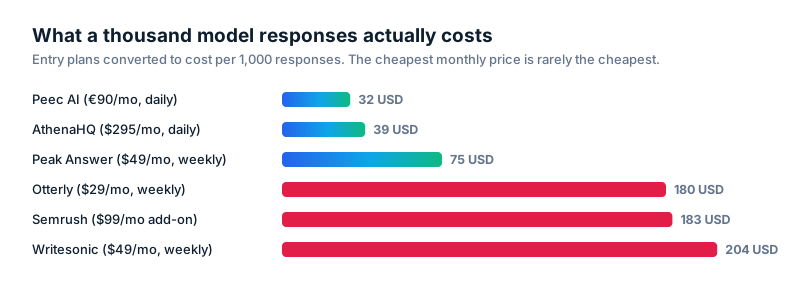
TL;DR: Headline prices in this category are close to meaningless because every vendor prices in a different unit. Converted to cost per thousand model responses, the ordering changes completely: the cheapest monthly price is often the most expensive per unit, and the most expensive monthly price is sometimes the cheapest.
Why headline prices mislead
Vendors price in "prompts", "credits", "queries", "tracked keywords" and "brands". None of those are the same unit, and none of them is the thing you consume.
What you actually consume is model responses per month: questions × engines × frequency. Twenty questions across six engines measured weekly is 480 responses. The same twenty questions across five engines measured daily is 3,000. Those are wildly different products at similar headline prices.
The conversion
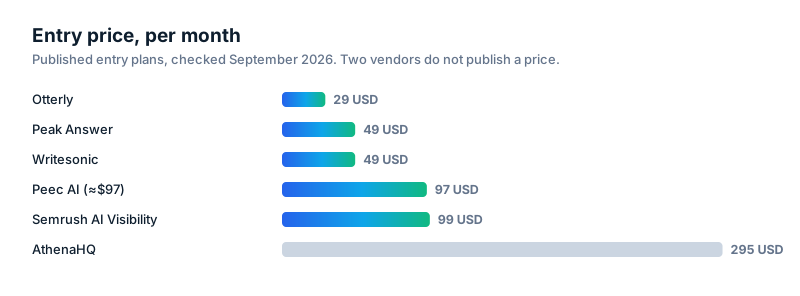
| Tool | Entry price | Engines | Refresh | Questions | Responses/month | Cost per 1,000 |
|---|---|---|---|---|---|---|
| Peec AI | €90/mo | 5 | Daily | 20 | ~3,000 | ~$32 |
| AthenaHQ | $295/mo | 5 | Daily | 50 | ~7,500 | ~$39 |
| Peak Answer | $49/mo | 6 | Weekly | 25 | ~650 | ~$75 |
| Otterly | $29/mo | 4 | Weekly | 10 | ~160 | ~$180 |
| Semrush AI Visibility | $99/mo | 5 | Weekly | 25 | ~540 | ~$183 |
| Writesonic | $49/mo | 4 | Weekly | 15 | ~240 | ~$204 |
| Profound | Quoted | 5+ | Daily | High | Very high | Not published |
| Scrunch AI | Quoted | 5 | Varies | n/a | n/a | Not published |
Figures checked September 2026, rounded, based on published entry plans. Verify before buying.
What each one does after it has measured
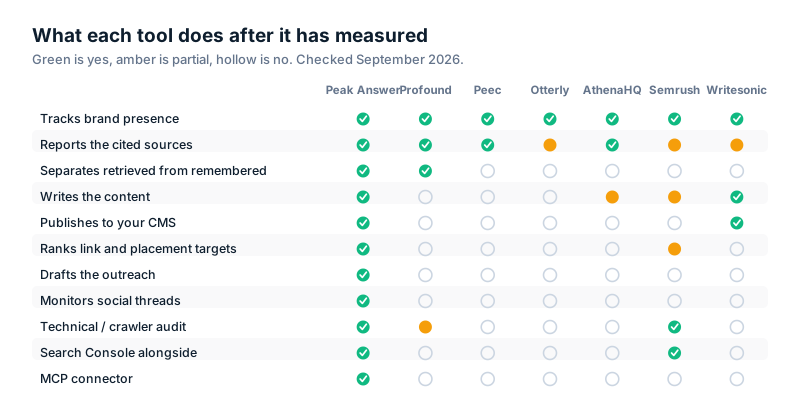
The rows that separate these products are the bottom seven, not the top two. Everything here tracks brand presence. The question is what happens next, and whether anybody at your end is going to do it if the product does not.
What the measurement actually says
Most writing in this category is advice. This section is the measurement behind it, and it is ours: fourteen markets measured end to end, and 505 tracking runs on our own category.
How winnable a market is varies more than anyone admits
We measured fourteen markets with the same engine the product runs for customers, scoring every domain the engines cited. The entry bar - how small a cited site can be and still get quoted - ranged from 12 to 66 out of 100.
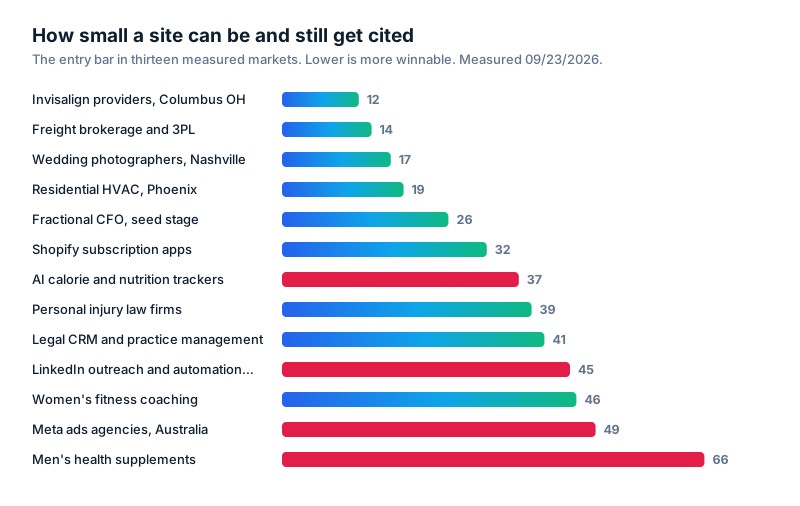
That is the difference between a quarter of work and a year of it, in the same discipline, decided entirely by which market you are in. Any vendor quoting one timeline has measured one market at most.
In Invisalign providers in a single city the bar was 12 and the typical cited site scored 25: a handful of well-made procedure and cost pages clears it. In men's health supplements the bar was 66 and GNC, a national retail chain, scored 62 and cleared it on one question in three, because the engines answer health questions out of medical sources and will not name a shop.
In most markets, your own site is not what gets cited
Content share is the proportion of cited sources that are somebody else's article rather than any vendor's own page. In nine of fourteen markets it was 100%.
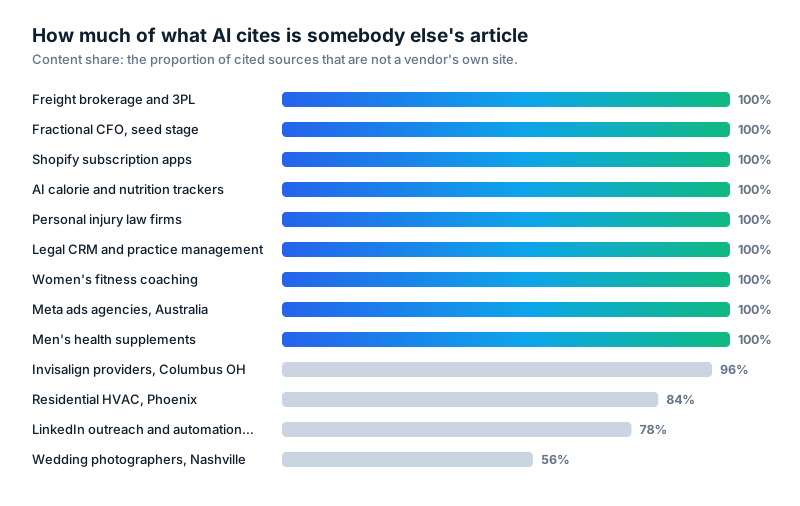
In those nine, publishing more of your own content cannot put you in the answer, because no vendor's own content is being cited at all. The mechanism is editorial: being named inside the pages that do get cited. The one outlier was wedding photography at 56%, where the answer to the question is a list of photographers and the engines cite their portfolios directly.
This is the single most useful thing to know before choosing a tool, and almost none of them will tell you, because almost none of them report at the source level.
The gap between the floor and the middle is where newcomers get in
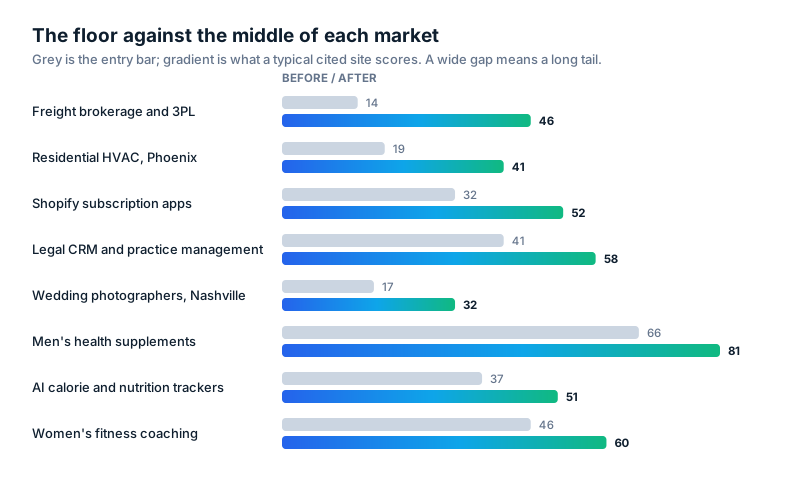
A wide gap means the engines are citing a few large publications and, underneath them, a scattering of much smaller sites. That tail is the opening. Freight brokerage had a bar of 14 against a median of 46, the widest spread we measured, and almost any serious page clears 14.
A narrow gap means the opposite. LinkedIn outreach tools had a bar of 45 against a median of 49 - four points - which means every cited site is roughly the same size and nothing small is getting in underneath.
We ran the same study on this category
505 tracking runs, 22 buying questions, every citation recorded and attributed to the question that produced it.
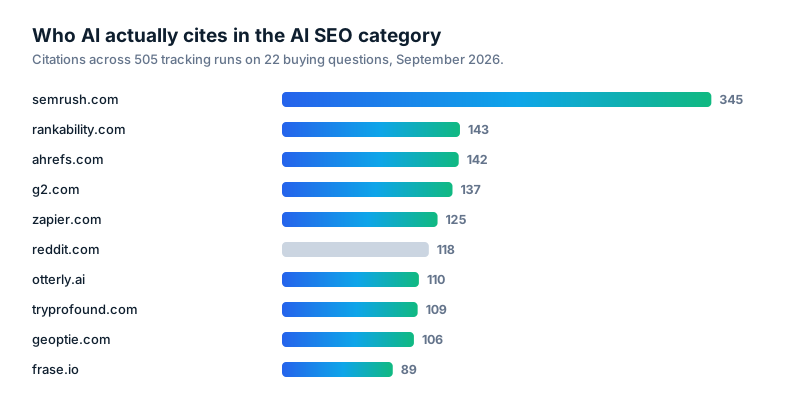
Two things fell out of it. Semrush at 345 citations is nearly two and a half times the next domain, and it is cited on use case, pricing and category questions rather than comparison ones: the engines reach for established publishers when the question is general. And Reddit at 118 citations is a top-ten source, which is the most actionable line on this page for a small company. You cannot become Semrush. You can answer a question in a thread.
The question type that quietly wastes a measurement budget
Six of our 22 questions were "alternatives to [competitor]". Those six produced most of the competitor citations in the whole study.
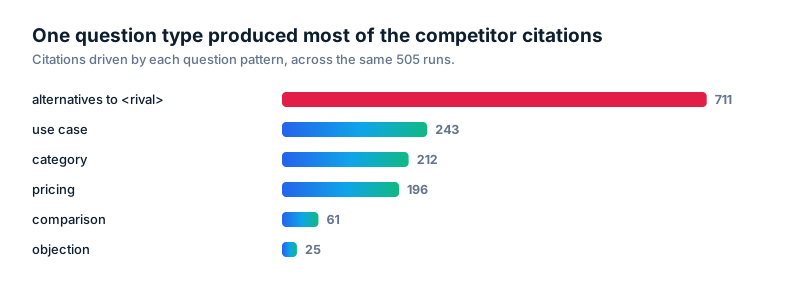
Obvious on reflection and we had not reflected on it: asking an engine to enumerate a competitor's alternatives returns competitors, cited from competitor comparison pages, none of which is a site you can get a link from. We cut that question type from six to two. The signal was worth having once; it was not worth a quarter of the budget every week.
If you are evaluating tools, this is worth checking in whatever you buy. Look at what your prompt set is made of, and look at what the citations come back as. A set made entirely of vendor-selection questions can only ever produce a citation list of vendors.
The one distinction that decides which work pays
Everything else on this page is detail. This is the thing to get right.
An AI engine answers in one of two ways, and they need opposite fixes.
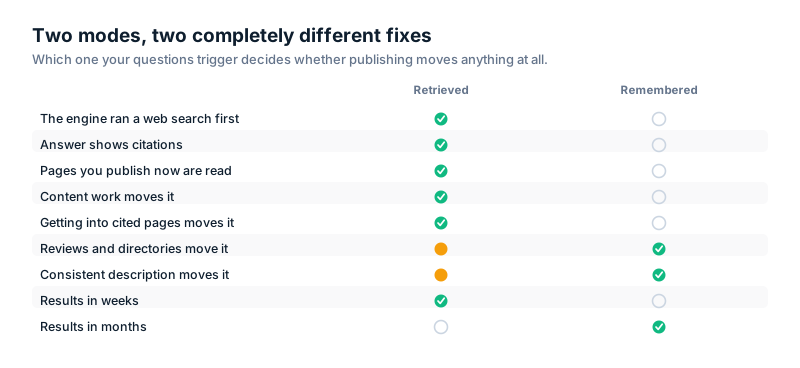
Retrieved. The engine ran a web search, read a handful of pages, and summarised them. Those pages decide the answer. Content and placement work, and they work in weeks, and a small company can win because the engine is summarising documents rather than ranking brands.
Remembered. The engine answered from training data that closed months ago. Nothing you publish this quarter will be read, because nothing is being read. Only breadth of presence moves it: reviews, directories, consistent description, over months.
Work on the wrong one and you get no result and no explanation, which is how a year disappears. So the question to ask any vendor is not how many engines they track. It is whether they will tell you, per question, which of these two you are facing.
Most of this category cannot. It is the row in the feature table worth more than the other fourteen put together.
What the conversion reveals
Daily refresh is the dominant variable. Peec at €90 and AthenaHQ at $295 look expensive and are the two cheapest per response, because they measure seven times as often. That is only value if you will act on it seven times as often — most teams will not, and are better off paying more per response for fewer of them.
The cheapest monthly price is the most expensive per response. Otterly at $29 costs roughly five times more per thousand responses than Peec at €90. Otterly is still the right answer for a small question set; it stops being the right answer the moment you grow.
Weekly at six engines sits in the middle, which is where most businesses should be: enough frequency to notice change, enough coverage to not miss an engine.
But cost per response is not the whole decision
It measures one thing and there are three others.
Does anything happen after the measurement? Peak Answer, Writesonic and partly AthenaHQ act on findings; the rest report. A reporting tool that is cheap per response is still producing homework rather than outcomes if nobody will do the work.
Does it tell you which mode an answer came from? Retrieved answers move with content and placement; remembered ones do not. Most of this category cannot distinguish them, and a cheap measurement pointing you at the wrong work is not cheap.
Does it show the sources? The cited set is what tells you what to do next.
Choosing by budget
Under $50/mo. Otterly if you only need measurement and have a small question set. Peak Answer if you need the work done as well.
$50–150/mo. Peak Answer or Peec, depending on whether you want execution or daily cadence. Semrush's add-on if you are already paying for Semrush and consolidation matters more than depth.
$150–400/mo. AthenaHQ if you have several brands. Otherwise you are probably over-buying unless the daily refresh is genuinely used.
Enterprise. Profound for analysis depth, Scrunch for crawler and agent access, frequently both.
Frequently asked questions
What is the cheapest AI visibility tool?
Otterly at $29/mo by headline price. Peec AI at roughly $32 per thousand responses by unit cost. Those are different questions with different answers.
Is daily tracking worth paying for?
Only if you act on it. If your content cycle is monthly, daily measurement is precision you will not use.
Do any of these have a free tier?
Free trials rather than free tiers. Permanently free continuous measurement does not exist, because the queries cost the vendor real money.
How many questions should I track?
Twenty well-chosen buying questions, measured weekly, is enough for most businesses and is the number this page's conversions assume.
Will prices change?
Constantly. Everything here was checked September 2026 and should be verified before you buy.